Canada’s time zone madness · ↗ thedatacopywriter.substack.com
Time zones are a funny thing, but no one was laughing when the clocks changed (or didn’t) this November 1st in Canada. As Eric Cai explains, parts British Columbia, Alberta, Manitoba, the Northwest Territories, and parts of Ontario have decided to adopt permanent Daylight Saving Time this year. This change covers nearly a third of Canada’s population. (British Colombia led the pack here—which I mentioned in my post on the whimsy of the Time Zone Database.)
Microsoft calendars have not coped well with the new transitions (or rather, lack of them) and neither have cells phones, leading to chaos in scheduling across time zones. Recommended work-arounds for affected users include setting your time zone to Bogotá, Colombia.
Somehow, this new temporal regime has also resulted in a part of British Colombia (on the West coast) observing the same time as a part of Florida (on the East coast).
The only thing worse than changing the clocks once per year is suddenly not changing them, apparently.
So, did El Salvador invade Haiti? · ↗ www.theguardian.com
The Guardian has some good reporting on El Salvador’s widening military mission in Haiti. After four Salvadoran personnel were kidnapped by Haitian gangs on October 18, President Nayib Bukele responded by sending more than 2,000 troops to Haiti. The new deployment of Salvadoran troops are operating outside the existing UN-backed Gang Suppression Force.
It’s an ambitious operation for a country of just six million people, only a few years out from its own brutal but effective crackdown on gangs. Apparently, Bukele has decided Haiti’s gangs are next on the list.
Little Muddy wrote itself into a rut · ↗ lm.jprs.me
Results from a thirty-day experiment in autonomous blogging
I ran a month-long experiment in autonomous blogging from August 22 to September 20, which I called Little Muddy. The idea was to describe the form of this blog (without giving it any actual posts) and let GPT-5.6 Sol do its own thing for selecting topics and writing posts. Here is how I described the parameters of the experiment:
For the next thirty days, GPT-5.6 Sol will choose a topic, research it if necessary, write a post, and publish it once a day without any intervention from me.
I have given it a fixed editorial guide loosely describing the style, habits, and subject matter of Big Muddy, along with a suggested length of 150–500 words. It has access to web search, but I give no guidance beyond Big Muddy’s broad categories as to what to write about. It also gets the complete archive of previous Little Muddy posts so it doesn’t write the same post twice, and so it can make organic callbacks when they arise. Oh, and it has a (low) spending cap, so it doesn’t go crazy with the research.
The intention of the archive was to avoid duplication of topics and to allow for posts to link back to earlier, relevant posts, which I frequently do on Big Muddy. I did not intend for the archive to serve as a template for future posts.
…ChatGPT, know thyself
AIs should know their own capabilities and product features
I recently became annoyed by a longstanding bug with ChatGPT’s “archived chats” feature. When you archive a chat, it’s supposed to retain its project label, if it was inside a project when you archived it.
On desktop (but not mobile), the “archived chats” section in the settings has a filter for project. However, for as long as I can remember, all chats have appeared under “No project”—the project filter is always blank. However, clicking the button to unarchive a chat returns it to the correct project. So the project labels are still there, it’s just that the archived chats interface is unable to make use of this information.
I then made my first mistake: I asked ChatGPT for help. It ran through some basic diagnostics, and I confirmed I was unable to fix the problem. Then I asked how I could report a bug. Here was the response:
The official way to report a ChatGPT bug is through OpenAI Support.
- Go to help.openai.com.
- Click the chat bubble in the bottom-right corner.
- Start a new support conversation.
- Indicate that you’re reporting a ChatGPT bug and describe the problem.
Great! I fired up the AI support chat and announced, “I have a bug report.” The agent walked me through some more testing and we created a thorough bug report. And when it came time to submit that report?
…Most folk wisdom about LLMs is outdated · ↗ zou-group.github.io
This is a neat paper from Owen Queen and James Zou of Standford University: “The shelf life of LLM findings”. The authors revisited 50 widely cited claims about LLMs and found that most either no longer held or had significantly weakened across 20 models. These claims operate as bits of folk wisdom people carry about with them and shape public understanding of LLM capabilities, especially among those that are not frequent users of AI. It is instructive to see quantified just how quickly many of these claims became out of date.
For example, until mid-2026 models would frequently fabricate scholarly citations, but this behaviour has much reduced among most recent models (though even if only 1% of citations are fabricated, models still do this far, far more often than humans, who are prone to misrepresenting the content of citations, rather than inventing references wholesale).
Another slightly dubious “expired” claim is that models no longer refuse obviously harmless requests. This may be true according to the methods of the original 2023 paper, but certainly we still have high-profile refusals like Fable being unwilling to discuss the powerhouse of the cell and other basic biological concepts. So this bit of wisdom is not entirely out-of-date.
Interestingly, three of their 50 claims had actually strengthened relative to the original research: models praise what their users like, LLM judges favor their own writing, and random-number requests favor a few answers.
…Why not make research grants a literal lottery?
An article in Nature highlights the trend of declining acceptance rates for research grants: “Is research funding now a lottery? Elite funder ERC swamped by applications”. The latest European Research Council’s Starting Grant competition will have a success rate of under 5%. Many other granting programs across academia face similarly abysmal odds.
AI is contributing to the problem of a skyrocketing number of applications targeting a fixed number of prizes, as preparing a competent grant application is easier than ever. Still, the current system consumes a tremendous amount of time and energy from both the researchers submitting the grant applications and the organizations and peer reviewers adjudicating them. AI will only accelerate this arms race, with applicants producing ever-more elaborate proposals and reviewers having to sift through them (or get their AIs to do so). Yet failure is near-guaranteed.
Maybe we should stop pretending this system can reliably discriminate among dozens or hundreds of basically good proposals. If applying for a major grant is like a lottery now, then why not make it a literal lottery? It would save everyone a lot of time and heartbreak if applicants were allowed to submit much shorter proposals, subject to a basic quality screen, to be chosen by a random lottery. In fact, this system and variations on it have already been tried across a number of funders and countries.
…Ted Gioia’s practical advice on public speaking · ↗ www.honest-broker.com
I’ve never been particularly terrified of public speaking. It’s a lot like diving into cold water: sure, there’s a lot of anxiety before you take the plunge, but once you’re in the water, you just have to start swimming.
That being said, I’ve never been particularly good at public speaking, either.
Ted Gioia’s article “Ted’s 10 Rules for Public Speaking” is the best, most pragmatic advice I’ve ever read on the subject. I will definitely be reviewing it the next time I have to give a talk. There’s some good stuff in the comments, too.
Fake statistics and LLM citation laundering · ↗ peec.ai
The (in)ability of AI to evaluate sources is a bit of a preoccupation on this blog. In a post from last month, Metehan Yesilyurt described an experiment he ran to seed the web with fake statistics. He generated 50,000 fake statistics pages and 15,000 listicles for about $50 USD and added them to a brand new website, StateGlobe. Over seven months, he managed to get over 300 domains linking to his site and even a handful of citations in academic, financial, and other publications. This despite the fact that Google, to its credit, quickly deindexed his site, cutting off a huge source of traffic.
Why did it continue to succeed? AI bots. In the thirty days before the post, the site received 600,000 bot requests, including 72,000 from ChatGPT’s page-fetching bot. Over the course of the experiment, ChatGPT referred over 10,000 sessions to his site.
Part of why this problem is particularly pernicious is because, as the author points out, citation laundering means these stats from a random website can eventually be cited by something more authoritative-looking, like an academic publication, which leads to others becoming much more willing to cite it.
I’ve discussed before the problem with LLMs increasingly intermediating our interactions with information on the internet, making it harder for us to judge the trustworthiness of sources. Experiments like this show that fear is justified.
…The last place you can do Shakespeare on TV
Remembering Patrick Stewart (1940–2026)
We lost Patrick Stewart on October 28. As a kid who grew up on Star Trek: The Next Generation, it was one of those rare celebrity deaths that hit me personally.
Patrick Stewart made TNG special. Prolific Star Trek guest star James Sloyan (who we also lost this year) once described TNG as the last place you could do Shakespeare on TV. Stewart, a classical Shakespearean actor, brought a gravitas to the role that elevated every script he was given. The show was never afraid to let a grand, carefully delivered monologue be the climax of its stories. Indeed, many of its best scenes and episodes could easily be transposed to the stage.
Sure, it was convenient from a production standpoint that many of the show’s episodes could consist entirely of people talking at each other on prebuilt sets, both to save money and for the sake of the gruelling production schedule. But it was Stewart who made it work through the unapologetic, unselfconscious theatricality he embodied on screen.
In a way, the most enduring contribution of Stewart’s TNG was its positive vision of liberalism. Captain Picard was restrained, rational, willing to be persuaded. He inhabited a world where individual and institutional competence could coexist with respect for individual rights, and where force could be brought to bear not out of anger or aggression, but in defence of others. Where progress was possible but not inevitable.
…The end of asking stupid questions in public
Twenty years ago, Yahoo Answers user kavya posted the now-iconic question “How is babby formed?” It’s the kind of naive, sincere, even ridiculous question that feels anachronistic on the modern internet. Yahoo Answers is long gone (too bad, it once helped me to identify a song from partially remembered lyrics) and Stack Overflow has fallen below 1,000 posts per month, an incomprehensible drop of over 99% from six years earlier. Sure, people still ask these types of question on Reddit, but now you can’t help but suspect that these threads are designed to provoke particular reactions from behind feigned innocence, given the wealth of options for quickly answering the questions posed.
It is true that “Let Me Google That For You” is almost as old as “How is babby formed?”, but at least ignorance on the internet used to be somewhat defensible, as searching the right terms and parsing the results required at least a modicum of effort.
But now you can ask an LLM almost anything, privately. It’s certainly the safer option for the question asker, who avoids the possibility of embarrassment (unless you have Grok’s Roast Mode on, if that’s still a thing). But it also means these questions will never create a cultural footprint. There will be no more “Babbys” or “The Dumbest Boy Alive”.
…Is philanthropy the future of academic publishing?
Normal people are often incredulous when you tell them about the model of academic publishing. Conversations tend to go something like this:
“Oh, you published an article, how much did they pay you?”
“Well, actually, I paid them.”
“Wait, so you just pay to publish?”
“Well, not quite, first it has to get past an editor and then a bunch of peer reviewers.”
“Oh, so that’s what the fees are paying for.”
“Well, actually peer reviewers are unpaid, and editors usually are too.”
“What?”
Academic publishing is a racket, and everybody knows it. Its profit margins are among the best in the business (nearly 40% for some large publishers). A lot of this depends on volunteer labour, which is getting increasingly scarce as the volume of article submissions ramps up (partly due to AI).
But the most important publication venue for many fields is arXiv (especially those related to computer science, physics, and math), the preprint server where research is free to publish and to read. Rather than conventional peer review, new authors generally need an endorsement to submit to a particular domain, and all papers are subject to basic screening. It went independent this year (it was previously housed in Cornell University) and hosts millions of papers on a budget of less than $7 million USD in 2025. At least in certain fields, arXiv is increasingly the terminal publication venue for many important papers, which receive extensive post-publication review and skip the traditional journal publishing model altogether.
…Where AI pulls its numbers · ↗ trakkr.ai
Trakkr just released an interesting report: they asked five AI assistants for a wide variety of statistics, and then traced 1,285 of the responses back to their original sources to determine whether the numbers could ultimately be supported by a study. Only 40% of claims could be. (Of course, just being able to find a study to support a statistic does not mean it is actually true or applicable, but it’s a start.)
This is not to say the AIs were generally hallucinating sources wholesale. In 8% of cases, a source was identified, but with a different value or context than reported. In 40% of cases, a source was named but either did not contain the statistic or was inaccessible or missing. In 11% of cases, the statistic was simply repeated everywhere with no attempt at a credible attribution, common on company blogspam sites that AIs still like to cite. The final 1% was when the rabbit hole ended at pages that would not load.
I have complained before about the poor performance of AIs in distinguishing the credibility of sources (sometimes to amusing/horrifying results). It’s neat to see an attempt to actually quantify this problem.
In defence of GitHub Issues
I saw a Reddit meme recently showing Squidward losing interest after seeing the GitHub issue count on Photocraft, the new vibe-coded Photoshop competitor.
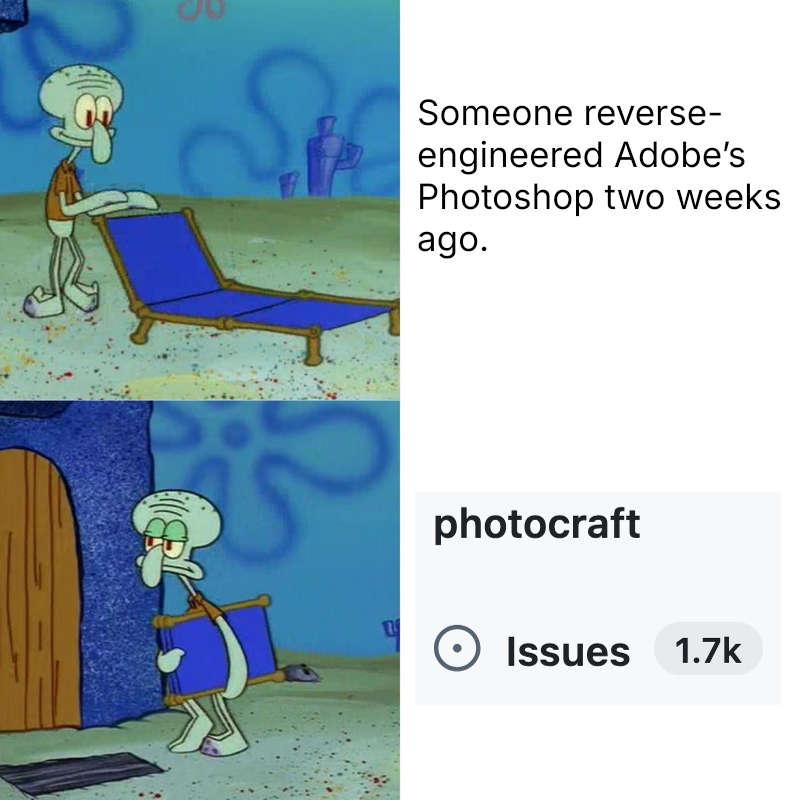 The assumption here seems to be 1,700 issues means 1,700 things broken, and thus the software isn’t really worth using. This may or may not be true of Photocraft in particular, but it does reflect a common misunderstanding of what issues are on GitHub.
Issues are, as any true software developer knows, used to raise not only bugs but feature requests, questions, and design decisions. A large number of issues does not inherently mean a project is in bad shape.
Issues are also not the only thing on GitHub that has a funny and counterintuitive name. Pull requests really should be called merge requests, and on competing development platform GitLab, they are. But “issues” is a surprisingly sticky term that is still used on both platforms.
At first blush, it seems like there should be an obviously better term for the functionality covered by “issues”. But it’s surprisingly hard to improve on:
…AI is making extremely niche software viable
AI is filling the Pathfinder character builder gap
I’ve always enjoyed perusing projects that make extremely complicated game systems legible. My gold standard is the Hitchhiker’s Guide to the Cataclysm, a companion tool to the open-source roguelike Cataclysm: Dark Days Ahead that automatically extracts information from the game’s GitHub repository and updates every twelve hours to keep up with the game’s daily updates.
The Pathfinder games developed by Owlcat Games, most recently Wrath of the Righteous, adapt the Pathfinder 1e tabletop system and would also benefit greatly from a companion tool. This is because the games feature a dizzying array of options for character builds—a dozen playable races, more than 150 classes and subclasses, and over 1,000 spells, feats, and abilities, each with their own prerequisites and restrictions (not to mention countless items to choose from). Players are relatively free to multiclass, which only adds to the complexity. For this reason, planning the journey from level 1 to level 20 is half the fun for many players. There’s a reason Pathfinder 1e is commonly called “Mathfinder”.
The problem is, there’s no convenient way to actually plan builds outside of the game. Your careful spreadsheet planning might be undone by forgetting that a particular ability becomes available at level 5 instead of level 4, or that a certain feat has a prerequisite that is only available at level 10. There’s no way to automatically test potential builds against the actual game rules to determine if they are valid.
…It’s time to come back to Firefox · ↗ www.youtube.com
I have never used Chrome on my personal computer outside of the occasional dev task or website incompatibility (and automated web scraping). I went straight from Netscape to Firefox, which means I have been using the Mozilla browser for at least twenty years now.
Firefox dropped an ad on Sunday with the title: “It’s time to come back to Firefox. The Internet you loved is still here.”
In May, I wrote a piece entitled “The best is over” lamenting the rise of hyperoptimized “content” and the disappearance of the amateur web. This ad captures that nostalgia pretty well, even opening with the same familiar face: the Numa Numa guy, Gary Brolsma.
The Twitter post is even more bittersweet:
How is the internet less private than in 2006, when the whole family shared one computer? Back then, the internet was weird, personal, and all of ours. So, we got your favorite meme legends back together to say it louder: What happened to the internet?
Here’s what happened: big tech tracking you everywhere, ads that follow you around, and AI you didn’t ask for.
While the internet got worse. Firefox got better. We’re built to protect, not track you, with AI on your terms, and ad blocker support.
It’s time to come back to Firefox.
…
Why I took my server off the public internet
It was the announcement of the PHP2Shell vulnerability last week that finally convinced me to take my personal server off the public internet.
For the past six months or so, particularly since Anthropic unveiled its Mythos model in April, cybersecurity experts have been warning of an impending cyber-apocalypse. Well, Black October is here. The discovery of these critical vulnerabilities in PHP, the programming language used by most websites, resulted in many services going dark as they rushed to patch their systems. This high-profile event has been accompanied by reports of other serious security flaws across widely used software. In fact, around 3% of all vulnerabilities recorded in the National Vulnerability Database since 1988 were reported in the past month alone.
For many years now, I have run a personal server to keep files synchronized across my computers, as well as to store my calendars and contacts. I used to run Nextcloud, but now I run OpenCloud and Radicale for a more lightweight experience. I also run Pinepods as a podcast server.
I decided to put it all behind Tailscale, which creates a mesh VPN to directly link your devices together. This means that my server can speak directly to my computers and my phone while blocking all public inbound connections.
The basic setup was extremely straightforward (and free for personal use). The more interesting problem arose when I tried to figure out how difficult it would be to keep my existing domains and subdomains, both because I like the URLs and because I wanted to avoid having to reconfigure the clients using them.
…The “once-only” principle
When you move, the government of Canada warns you:
To keep getting your benefits, payments and services, you must change your address with each government department or agency. Your new address is not shared automatically because government systems aren’t connected.
My home province of Quebec is better, operating a service that allows you to simultaneously change your address with seven important departments and organizations, including those responsible for your driver’s licence, health insurance, and voter registration.
Estonia, on the other hand, is famous for its digital government. It operates on the “once-only” principle: citizens provide their data (like an address) only once, and it is reused across government agencies.
This seems remarkable to a Canadian. It isn’t uncommon to have to provide my address multiple times on different forms as part of the same submission.
Estonia isn’t unique in this principle, although it is probably the best-known example. Other European countries have similar arrangements, helped by their longstanding tradition of maintaining comprehensive population registers.
Updating seven agencies at once is nice, but the point of the “once-only” principle is that you shouldn’t have to update seven agencies in the first place.
Let flags be ugly · ↗ www.worksinprogress.news
I’ve long been a bit of a flag enjoyer (thanks, Paradox), so this article by Ned Donovan has really stuck with me: “Good design is ruining American flags”. Using a rather vivid metaphor of banditry in rural India, the author laments the convergence of American municipal flags towards simple, technically sound designs that fail only at a flag’s most important task: to distinguish.
From the article:
The British did to highway robbery exactly what the refiners do to flags. They took something various and local and difficult, and made it simple enough to draw from memory. Twenty cities, one flag. Stand a man from Tulsa in front of the winning twenty and he could not find his own.
For national flags, I am a strong supporter of flags that are bold and simple enough to draw from memory. But the subnational flag space is significantly more crowded, and you need to do a lot more to stand out. If that means offending the sensibilities of the North American Vexillological Association, then so be it.
Let flags be ugly.
PS. I will admit the flag for Newton, Kansas is awesome, though.

Another day, another fake pollster · ↗ blog.fiftyplusone.news
On Wednesday, I wrote about the exposure of fake pollster Wedgewood Polls by polling aggregator FiftyPlusOne. Yesterday, the team uncovered another questionable pollster, SoCal Strategies, which was apparently associated with Wedgewood. Shortly after FiftyPlusOne interviewed a person affiliated with the firm, its entire web presence disappeared, including its website, Twitter account, and Substack.
In response, FiftyPlusOne announced that it would remove two suspicious polls from its database, though earlier surveys conducted by the organization will remain. The allegations apparently concerned only a subset of the firm’s polls.
Some evidence of the slopocalypse in government
Sam Freedman has some links in his recent article “Drowning in slop” relevant to my recent posts about how AI agents will overwhelm trust-based institutions, including requests, inquiries, complaints, and other kinds of submissions to various government agencies.
The first link is to this July 2026 preprint from Google about how Americans use Gemini, which showed that a little over 1% of non-work conversational AI queries were about using government services (see Figure 14B). By contrast, the share of non-work active time dedicated to using government services is barely distinguishable from zero, or as the paper puts it:
The biggest relative outlier is “Government Services & Civic Obligations”, which has almost a twenty-fold higher representation in AI usage than human activities.
A similar study of conversations with Claude found 1.07% related to “government navigation, immigration and visa guidance, and tax advice and compliance”, which is very close to the Google figure.
The second link is to this August 2026 preprint entitled “Characterizing Agentic Flooding of Government Services”. It documents rising numbers of submissions to various government since the introduction of ChatGPT, across domains including air passenger rights claims, ombudsman complaints, administrative court litigation, and freedom of information requests. While the authors could not directly establish the proportions of the increases attributable to AI, the reported pattern is certainly consistent with my fear of people copy and pasting slop into government submission forms (and increasingly, agents submitting slop themselves directly).
…It was just a polling experiment, bro · ↗ blog.fiftyplusone.news
Another fake pollster gets outed
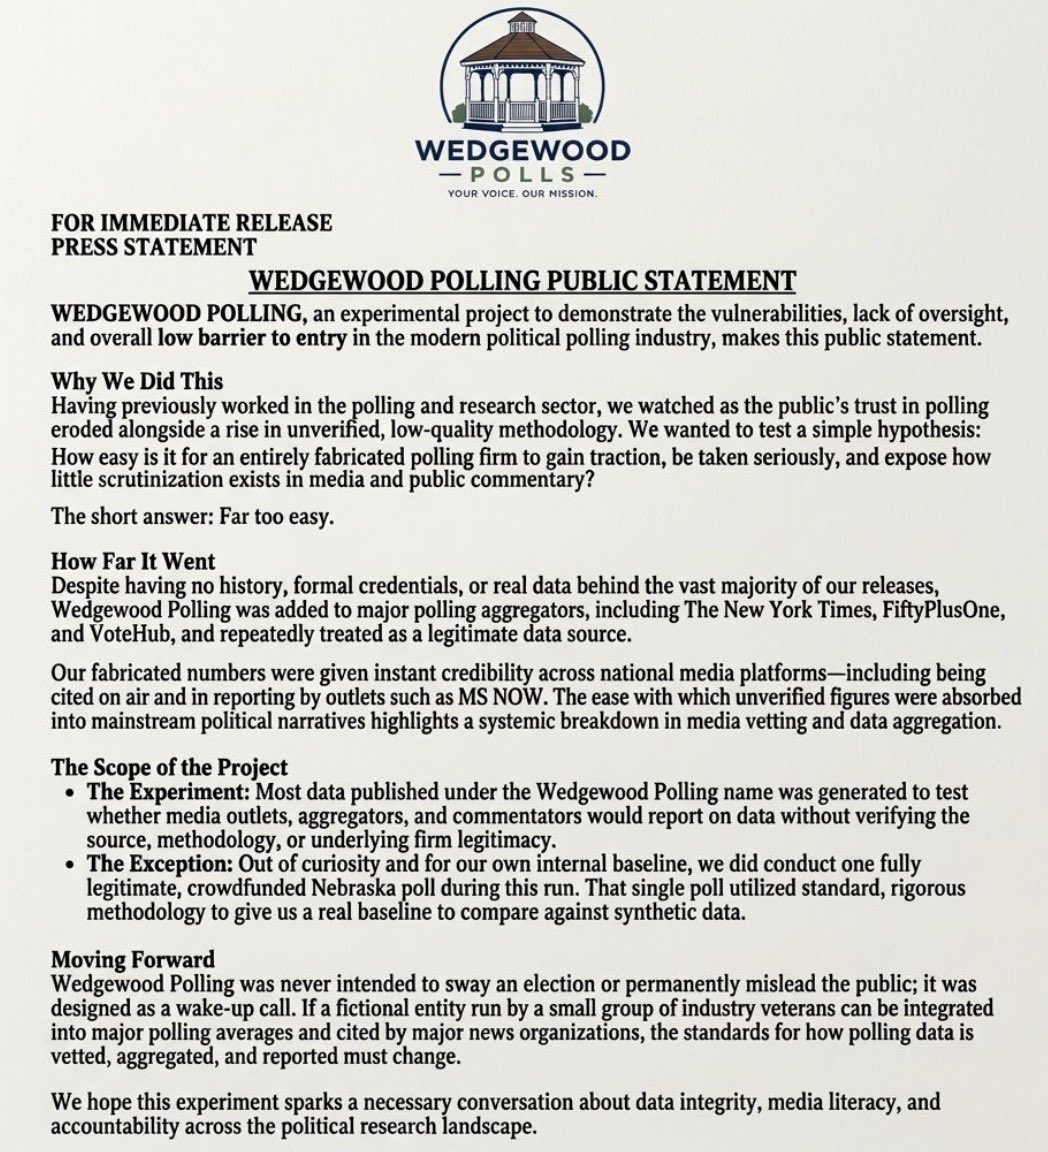
In August, I wrote about the exposé of fake pollster Median Strategies. Yesterday, the team over at poll aggregator FiftyPlusOne exposed yet another fake pollster: Wedgewood Polls. Their suspicions were confirmed after receiving raw data from the firm that had both statistical issues and methodological issues related to the polling platform they claimed to have used (they paid to run an actual poll on said platform as part of their investigation).
Unlike Median Strategies, polls from Wedgewood did make it into several major polling aggregators, including FiftyPlusOne and The New York Times.
Shortly after being contacted by FiftyPlusOne, the fake pollster posted the following statement to Twitter:
I want to give AI agents access to my bank account
But I want to run it on my computer, not someone else’s
Citigroup and Bank of America are the latest American financial institutions to restrict AI agents’ access to customers’ accounts:
Citi says it does not permit “third-party AI agents or assistants to log into a customer’s account or transact directly within our digital banking platforms” […] The bank says customers can still authorise limited, read-only access to account data with certain open-banking providers.
I would like very much to give an AI agent access to mine.
Not permission to move money, of course. But I do want an agent to analyze my transactions, identify patterns and outliers, and prepare a monthly financial audit for me. Today’s local AI models are more than capable of this. There is no reason my personal financial data needs to leave my computer.
In March, I wrote about Canada’s plans for an open banking system. Seven months later, the core data-sharing provisions are not yet in place. Annoyingly, the proposed system seems to be designed around granting access to accredited third parties rather than allowing consumers to directly access their own data through an API. From the Consumer-Driven Banking Act:
The purpose of this Act is to establish a framework within which consumers, including businesses, can direct that their data be shared among participating entities of their choice
I want to give software running on my own computer read-only access to my bank accounts. Open banking should make that possible.
Some thoughts on Primetime
Chris Hansen as horror villain
A few weeks ago, I wrote about the ethics of true crime, including To Catch a Predator, the electric Dateline series from the mid-aughts about journalist Chris Hansen confronting men who arrived at a house expecting to meet minors for sex. I described myself as a fan of the show, despite some reservations about the show’s methods. At the time, I was looking forward to seeing Primetime, Lance Oppenheim’s fictionalized account of the show’s disastrous Murphy, Texas investigation, which ended in the suicide of assistant district attorney Bill Conradt as police and television cameras arrived at his home. TCaP was ultimately canned by the network in the wake of these events.
I saw the film on opening night (September 25), albeit the French-dubbed version. What follows are some thoughts based on the notes I took after watching.
Robert Pattinson’s Chris Hansen is a heightened creation. I can’t speak to his vocal performance, but his physical performance is formidable. Much of the film is shot like a horror movie, with Hansen as the villain. The character reminded me at times of Jake Gyllenhaal as Louis Bloom in Nightcrawler.
Hansen is often shot in the same oversaturated, hyperreal colours that you see on the CRT monitors displaying footage from the stings. The man making the television show takes on the appearance of the images he is creating, the monster of the screens. Dan, the young decoy and protégé of Hansen, sometimes receives the same chromatic treatment.
…I do want a coffee
On the Spanish negative interrogative and the English emphatic do
My girlfriend is a native Spanish speaker. When we first started seeing each other, I noticed she had a tendency to phrase questions in the negative.
“You don’t want a coffee?”
In the original Spanish: ¿No quieres un café?
At first, it really bothered me. In English, this kind of question sounds as though the speaker assumes I’ve already decided against having a coffee. It feels vaguely hostile. When I pressed her on it, it turned out that this phrasing, the negative interrogative, is common in Spanish and does not necessarily carry the same negative connotation. In Spanish, adding the negative can make the question more of an invitation compared to the base form (“Do you want a coffee?”), without changing the essential meaning of the question. It carries none of the presumptuousness I sensed in English.
Naturally, I picked up this way of asking questions myself.
English has a construction I appreciate for a similar reason: the emphatic do. It changes the emphasis of a sentence without changing its essential meaning. Spanish can express the same emphasis in other ways, but lacks this particular grammatical construction.
Perhaps the most famous example is from Peter Pan: “I do believe in fairies! I do! I do!”
And I do want a coffee. Most of the time, anyway.
AI agents will DDoS trust-based institutions
I’ve filed a number of Access to Information requests (ATIPs, or FOIA requests for my American readers) in my time, and I’m always surprised there aren’t…more of them. The federal government received just under 34,000 requests across all institutions in the 2024–25 fiscal year. In a country of around 40 million people, that doesn’t seem like very many, especially since ATIPs are an important tool for many journalists. (Note: This excludes Access to Information requests to Canada’s immigration agency, which account for the vast majority of federal ATI requests but are mostly requests for immigration files rather than the kind of spammable public records requests I refer to in this article.)
Since 2016, you have never had to pay more than the initial $5 filing fee. In searching the government’s public list of completed requests, I have come across some pretty nutty ones, like people demanding proof for the existence of various viruses (or even any virus—yes, there is a conspiracy theory that viruses are not real). So the constraint on filing ATIPs isn’t really financial; it’s a question of time and attention.
Many components of our society rely upon this simple constraint: abusing them is tedious.
Yes, you could file endless complaints, appeal every decision, and escalate each dispute. Some people are bloody-minded enough to stay on the phone for five hours to get a $20 refund. But most people rationally give up. This is time-and-attention arbitrage.
…The problem with cheap but scarce daycare
Who gets access when everyone qualifies?
There is a scandal unfolding in British Columbia as the embattled premier, David Eby, revealed his family has a $10/day daycare spot. Subsidized $10/day daycare has rolled out unevenly across Canada. B.C. began its own $10/day pilot in 2018, while the federal government launched its Canada-wide program in 2021 (Quebec began its own subsidized daycare program in the late 90s). Access to the program is not means-tested, but like many other services in Canada, only access to the waitlist is universal.
Eby subsequently explained that one of his children was already attending the daycare when it was designated a $10/day site. He also claimed to have “donated the difference” to his childcare provider in order to offset the financial subsidy his family does not need.
There is no evidence that Eby’s family received preferential treatment to get a $10/day spot (although some wonder why a daycare in Vancouver’s wealthy Point Grey neighbourhood would receive a $10/day designation from the province in the first place). And his case does not illustrate a wealthy family somehow jumping the waitlist for subsidized daycare: his child was already enrolled before the designation.
But this scandal does remind me of the general trend here: when subsidized daycare spaces are scarce, access favours families with the time, flexibility, and knowledge to work the system. White-collar professionals are more likely to have the means to answer calls during business hours, visit facilities on short notice, and pay to reserve spots before they need them.
…Dzigurski Bench · ↗ github.com
Twelve AI models struggle to identify a still frame
This is the third time I am returning to the well of my mild bemusement over ChatGPT’s failure to identify a still frame from Sergio Leone’s Once Upon a Time in the West, which depicts railroad baron Morton (Gabriele Ferzetti) standing before a seascape by Serbian-American painter Alexander Dzigurski in his private railway car, with Frank (Henry Fonda) seated in the background. This exact frame appears on numerous publicly indexed websites.
In my two previous posts, ChatGPT’s GPT-5.6 Sol gave two confidently wrong identifications (_Jaws_ and _Sleuth_) over the trivially discoverable correct answer from a reverse image search.
This time, I decided to make a silly benchmark of this situation. Presenting: Dzigurski Bench (GitHub repository).
The task is simple. Respond to the following prompt:
What film is this image from?
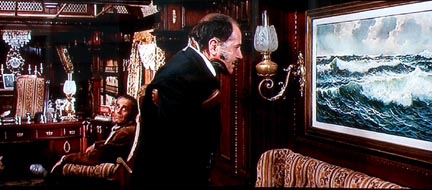
I ran the benchmark through OpenRouter using twelve models and three conditions:
| Condition | Tools available |
|---|---|
vision | None |
web | OpenRouter web search and page fetch |
web+lens | Web search, page fetch, and reverse_image_search() |
OpenRouter’s ordinary web search accepts text queries, not images. The custom reverse_image_search() tool simply returns the cached results of a Google Lens search identifying the still, to answer my earlier question of “will the models use reverse image search if it is dangled in front of them?”
Everyone cannot audit their own hardware
Another failure of crypto self-custody
In August, I wrote about why everyone cannot be their own bank, following the theft of $116 million in Bitcoin from users of the Coldcard hardware wallet, which suffered from a vulnerability in how it generated keys. In that post, I asked:
Do you trust the developers of a hardware wallet and trust that the device was not tampered with en route to you?
Well, here we are again.
This time, Ledger hardware wallets sold by an authorized reseller in Malaysia were found to have been modified with hardware capable of reading and transmitting the 24-word recovery phrases displayed during setup. Similar tampering has been reported elsewhere in the world, although these cases are so far unverified by Ledger. The attack has been linked to an estimated $93 million in cryptocurrency stolen.
The reseller, CryptoBilis, was acquired earlier this year, with the former CEO claiming a confidentiality agreement prevented former staff from revealing that the company was under new management. This has led to speculation that the purchasers themselves were involved in the attack, although there is no evidence of this yet.
The lesson here is that, once again, crypto is not ready for mainstream adoption. A few in the community will chide the victims for their naivety: sure, they bought a hardware wallet from an authorized reseller, but did they do a full teardown to ensure no additional components were added to the device? But I think many more will quietly recognize this as another case of people who did everything they were supposed to losing everything with basically no recourse.
Who needs a state to attack the food supply? · ↗ www.france24.com
The falling cost of attacking critical infrastructure
Hundreds of supermarkets in France suffered a cyberattack that heated freezers and fridges up to 50°C, sparking fires and mass food spoilage. Grocery stores from the conglomerate Ahold Delhaize operating in the Netherlands, Belgium, and Luxembourg also suffered a security incident around the same time, affecting its online app, delivery system, and electronic price tags. There is currently no indication whether these attacks were related.
The refrigeration units in the French supermarkets were from manufacturer Danfoss, which claims the affected units were “running outdated firmware”. Back in August, Claroty’s Team82 announced a vulnerability that would allow an attacker to perform just such an attack on refrigeration units using a remote web interface, although there is no indication so far that this specific vulnerability was exploited in this case.
Why are supermarket fridges connected to the internet in the first place? Remote monitoring and maintenance, apparently. But this also massively increases the attack surface, not just of individual stores and their profit margins, but of the food supply itself.
An uncomfortable reality is that a lot of critical infrastructure is more vulnerable than we would hope. Could this attack be a rehearsal for a larger attack by a hostile state or well-organized terrorist group? It reminds me a bit of the mysterious 2013 Metcalf sniper attack, in which unidentified gunmen cut communications cables and seriously damaged 17 transformers at a California electrical substation, then disappeared without a trace. Some feared it was just preparation for a larger attack that thankfully never came.
…Why I built an MCP server for Big Muddy
I recently decided to take a step to simplify my publishing workflow at Big Muddy. As previously described, Big Muddy is a Git-backed Hugo blog managed using Sveltia CMS, with post scheduling handled by a triggered GitHub Actions workflow.
A vital component of the Big Muddy workflow is the note: a temporary document visible only to me that I use to capture links or ideas and some surrounding context, in order to later use them to write an actual post.
In May, I added an intelligence layer to Big Muddy with a ZeroClaw personal agent running on my Raspberry Pi. The agent had one purpose: receiving a link or idea, adding some context through dialogue or web searches, and saving it as a temporary note to the Big Muddy repo.
Despite my documented struggles with ZeroClaw, this workflow was basically working for me. However, in parallel, I continued to use ChatGPT to research other notes and ideas, in a way that my ZeroClaw setup was not particularly well suited to carrying out (i.e., when the research required was extensive). But this left some ideas well-synchronized with the Big Muddy repo (from ZeroClaw) and some scattered about random ChatGPT threads, unless I manually turned them into temporary notes. Of course, I could always ask ChatGPT to do the transfer via the GitHub connector, but this wasn’t the ideal, fenced-in mechanism to do so.
…