The “once-only” principle
When you move, the government of Canada warns you:
To keep getting your benefits, payments and services, you must change your address with each government department or agency. Your new address is not shared automatically because government systems aren’t connected.
My home province of Quebec is better, operating a service that allows you to simultaneously change your address with seven important departments and organizations, including those responsible for your driver’s licence, health insurance, and voter registration.
Estonia, on the other hand, is famous for its digital government. It operates on the “once-only” principle: citizens provide their data (like an address) only once, and it is reused across government agencies.
This seems remarkable to a Canadian. It isn’t uncommon to have to provide my address multiple times on different forms as part of the same submission.
Estonia isn’t unique in this principle, although it is probably the best-known example. Other European countries have similar arrangements, helped by their longstanding tradition of maintaining comprehensive population registers.
Updating seven agencies at once is nice, but the point of the “once-only” principle is that you shouldn’t have to update seven agencies in the first place.
Let flags be ugly · ↗ www.worksinprogress.news
I’ve long been a bit of a flag enjoyer (thanks, Paradox), so this article by Ned Donovan has really stuck with me: “Good design is ruining American flags”. Using a rather vivid metaphor of banditry in rural India, the author laments the convergence of American municipal flags towards simple, technically sound designs that fail only at a flag’s most important task: to distinguish.
From the article:
The British did to highway robbery exactly what the refiners do to flags. They took something various and local and difficult, and made it simple enough to draw from memory. Twenty cities, one flag. Stand a man from Tulsa in front of the winning twenty and he could not find his own.
For national flags, I am a strong supporter of flags that are bold and simple enough to draw from memory. But the subnational flag space is significantly more crowded, and you need to do a lot more to stand out. If that means offending the sensibilities of the North American Vexillological Association, then so be it.
Let flags be ugly.
PS. I will admit the flag for Newton, Kansas is awesome, though.

Another day, another fake pollster · ↗ blog.fiftyplusone.news
On Wednesday, I wrote about the exposure of fake pollster Wedgewood Polls by polling aggregator FiftyPlusOne. Yesterday, the team uncovered another questionable pollster, SoCal Strategies, which was apparently associated with Wedgewood. Shortly after FiftyPlusOne interviewed a person affiliated with the firm, its entire web presence disappeared, including its website, Twitter account, and Substack.
In response, FiftyPlusOne announced that it would remove two suspicious polls from its database, though earlier surveys conducted by the organization will remain. The allegations apparently concerned only a subset of the firm’s polls.
Some evidence of the slopocalypse in government
Sam Freedman has some links in his recent article “Drowning in slop” relevant to my recent posts about how AI agents will overwhelm trust-based institutions, including requests, inquiries, complaints, and other kinds of submissions to various government agencies.
The first link is to this July 2026 preprint from Google about how Americans use Gemini, which showed that a little over 1% of non-work conversational AI queries were about using government services (see Figure 14B). By contrast, the share of non-work active time dedicated to using government services is barely distinguishable from zero, or as the paper puts it:
The biggest relative outlier is “Government Services & Civic Obligations”, which has almost a twenty-fold higher representation in AI usage than human activities.
A similar study of conversations with Claude found 1.07% related to “government navigation, immigration and visa guidance, and tax advice and compliance”, which is very close to the Google figure.
The second link is to this August 2026 preprint entitled “Characterizing Agentic Flooding of Government Services”. It documents rising numbers of submissions to various government since the introduction of ChatGPT, across domains including air passenger rights claims, ombudsman complaints, administrative court litigation, and freedom of information requests. While the authors could not directly establish the proportions of the increases attributable to AI, the reported pattern is certainly consistent with my fear of people copy and pasting slop into government submission forms (and increasingly, agents submitting slop themselves directly).
…It was just a polling experiment, bro · ↗ blog.fiftyplusone.news
Another fake pollster gets outed
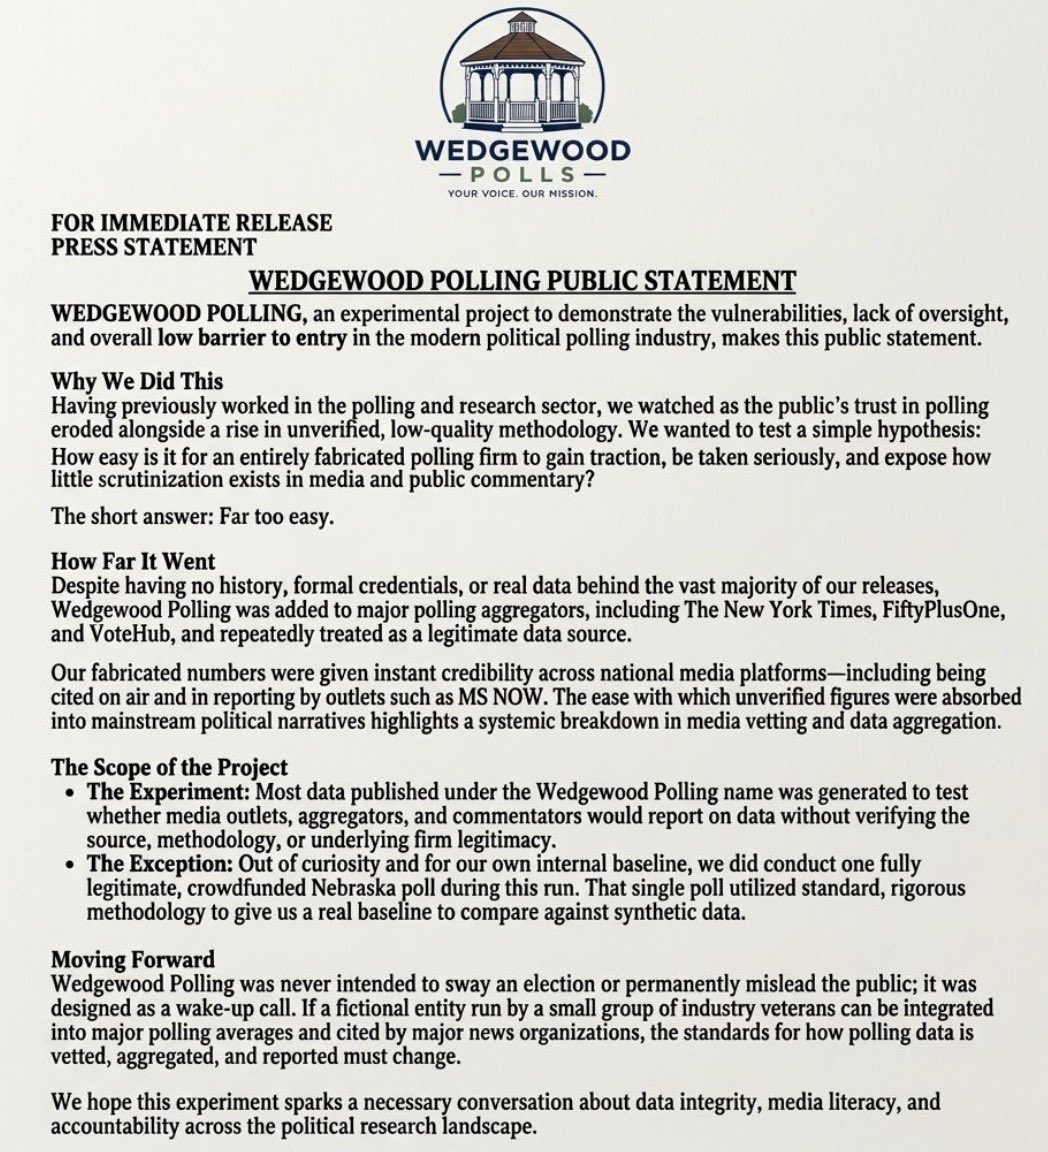
In August, I wrote about the exposé of fake pollster Median Strategies. Yesterday, the team over at poll aggregator FiftyPlusOne exposed yet another fake pollster: Wedgewood Polls. Their suspicions were confirmed after receiving raw data from the firm that had both statistical issues and methodological issues related to the polling platform they claimed to have used (they paid to run an actual poll on said platform as part of their investigation).
Unlike Median Strategies, polls from Wedgewood did make it into several major polling aggregators, including FiftyPlusOne and The New York Times.
Shortly after being contacted by FiftyPlusOne, the fake pollster posted the following statement to Twitter:
I want to give AI agents access to my bank account
But I want to run it on my computer, not someone else’s
Citigroup and Bank of America are the latest American financial institutions to restrict AI agents’ access to customers’ accounts:
Citi says it does not permit “third-party AI agents or assistants to log into a customer’s account or transact directly within our digital banking platforms” […] The bank says customers can still authorise limited, read-only access to account data with certain open-banking providers.
I would like very much to give an AI agent access to mine.
Not permission to move money, of course. But I do want an agent to analyze my transactions, identify patterns and outliers, and prepare a monthly financial audit for me. Today’s local AI models are more than capable of this. There is no reason my personal financial data needs to leave my computer.
In March, I wrote about Canada’s plans for an open banking system. Seven months later, the core data-sharing provisions are not yet in place. Annoyingly, the proposed system seems to be designed around granting access to accredited third parties rather than allowing consumers to directly access their own data through an API. From the Consumer-Driven Banking Act:
The purpose of this Act is to establish a framework within which consumers, including businesses, can direct that their data be shared among participating entities of their choice
I want to give software running on my own computer read-only access to my bank accounts. Open banking should make that possible.
Some thoughts on Primetime
Chris Hansen as horror villain
A few weeks ago, I wrote about the ethics of true crime, including To Catch a Predator, the electric Dateline series from the mid-aughts about journalist Chris Hansen confronting men who arrived at a house expecting to meet minors for sex. I described myself as a fan of the show, despite some reservations about the show’s methods. At the time, I was looking forward to seeing Primetime, Lance Oppenheim’s fictionalized account of the show’s disastrous Murphy, Texas investigation, which ended in the suicide of assistant district attorney Bill Conradt as police and television cameras arrived at his home. TCaP was ultimately canned by the network in the wake of these events.
I saw the film on opening night (September 25), albeit the French-dubbed version. What follows are some thoughts based on the notes I took after watching.
Robert Pattinson’s Chris Hansen is a heightened creation. I can’t speak to his vocal performance, but his physical performance is formidable. Much of the film is shot like a horror movie, with Hansen as the villain. The character reminded me at times of Jake Gyllenhaal as Louis Bloom in Nightcrawler.
Hansen is often shot in the same oversaturated, hyperreal colours that you see on the CRT monitors displaying footage from the stings. The man making the television show takes on the appearance of the images he is creating, the monster of the screens. Dan, the young decoy and protégé of Hansen, sometimes receives the same chromatic treatment.
…I do want a coffee
On the Spanish negative interrogative and the English emphatic do
My girlfriend is a native Spanish speaker. When we first started seeing each other, I noticed she had a tendency to phrase questions in the negative.
“You don’t want a coffee?”
In the original Spanish: ¿No quieres un café?
At first, it really bothered me. In English, this kind of question sounds as though the speaker assumes I’ve already decided against having a coffee. It feels vaguely hostile. When I pressed her on it, it turned out that this phrasing, the negative interrogative, is common in Spanish and does not necessarily carry the same negative connotation. In Spanish, adding the negative can make the question more of an invitation compared to the base form (“Do you want a coffee?”), without changing the essential meaning of the question. It carries none of the presumptuousness I sensed in English.
Naturally, I picked up this way of asking questions myself.
English has a construction I appreciate for a similar reason: the emphatic do. It changes the emphasis of a sentence without changing its essential meaning. Spanish can express the same emphasis in other ways, but lacks this particular grammatical construction.
Perhaps the most famous example is from Peter Pan: “I do believe in fairies! I do! I do!”
And I do want a coffee. Most of the time, anyway.
AI agents will DDoS trust-based institutions
I’ve filed a number of Access to Information requests (ATIPs, or FOIA requests for my American readers) in my time, and I’m always surprised there aren’t…more of them. The federal government received just under 34,000 requests across all institutions in the 2024–25 fiscal year. In a country of around 40 million people, that doesn’t seem like very many, especially since ATIPs are an important tool for many journalists. (Note: This excludes Access to Information requests to Canada’s immigration agency, which account for the vast majority of federal ATI requests but are mostly requests for immigration files rather than the kind of spammable public records requests I refer to in this article.)
Since 2016, you have never had to pay more than the initial $5 filing fee. In searching the government’s public list of completed requests, I have come across some pretty nutty ones, like people demanding proof for the existence of various viruses (or even any virus—yes, there is a conspiracy theory that viruses are not real). So the constraint on filing ATIPs isn’t really financial; it’s a question of time and attention.
Many components of our society rely upon this simple constraint: abusing them is tedious.
Yes, you could file endless complaints, appeal every decision, and escalate each dispute. Some people are bloody-minded enough to stay on the phone for five hours to get a $20 refund. But most people rationally give up. This is time-and-attention arbitrage.
…The problem with cheap but scarce daycare
Who gets access when everyone qualifies?
There is a scandal unfolding in British Columbia as the embattled premier, David Eby, revealed his family has a $10/day daycare spot. Subsidized $10/day daycare has rolled out unevenly across Canada. B.C. began its own $10/day pilot in 2018, while the federal government launched its Canada-wide program in 2021 (Quebec began its own subsidized daycare program in the late 90s). Access to the program is not means-tested, but like many other services in Canada, only access to the waitlist is universal.
Eby subsequently explained that one of his children was already attending the daycare when it was designated a $10/day site. He also claimed to have “donated the difference” to his childcare provider in order to offset the financial subsidy his family does not need.
There is no evidence that Eby’s family received preferential treatment to get a $10/day spot (although some wonder why a daycare in Vancouver’s wealthy Point Grey neighbourhood would receive a $10/day designation from the province in the first place). And his case does not illustrate a wealthy family somehow jumping the waitlist for subsidized daycare: his child was already enrolled before the designation.
But this scandal does remind me of the general trend here: when subsidized daycare spaces are scarce, access favours families with the time, flexibility, and knowledge to work the system. White-collar professionals are more likely to have the means to answer calls during business hours, visit facilities on short notice, and pay to reserve spots before they need them.
…Dzigurski Bench · ↗ github.com
Twelve AI models struggle to identify a still frame
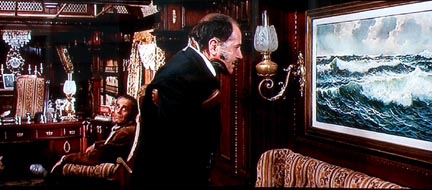
This is the third time I am returning to the well of my mild bemusement over ChatGPT’s failure to identify a still frame from Sergio Leone’s Once Upon a Time in the West, which depicts railroad baron Morton (Gabriele Ferzetti) standing before a seascape by Serbian-American painter Alexander Dzigurski in his private railway car, with Frank (Henry Fonda) seated in the background. This exact frame appears on numerous publicly indexed websites.
In my two previous posts, ChatGPT’s GPT-5.6 Sol gave two confidently wrong identifications (Jaws and Sleuth) over the trivially discoverable correct answer from a reverse image search.
This time, I decided to make a silly benchmark of this situation. Presenting: Dzigurski Bench.
The task is simple. Respond to the following prompt:
What film is this image from?
I ran the benchmark through OpenRouter using twelve models and three conditions:
| Condition | Tools available |
|---|---|
vision | None |
web | OpenRouter web search and page fetch |
web+lens | Web search, page fetch, and reverse_image_search() |
OpenRouter’s ordinary web search accepts text queries, not images. The custom reverse_image_search() tool simply returns the cached results of a Google Lens search identifying the still, to answer my earlier question of “will the models use reverse image search if it is dangled in front of them?”
Everyone cannot audit their own hardware
Another failure of crypto self-custody
In August, I wrote about why everyone cannot be their own bank, following the theft of $116 million in Bitcoin from users of the Coldcard hardware wallet, which suffered from a vulnerability in how it generated keys. In that post, I asked:
Do you trust the developers of a hardware wallet and trust that the device was not tampered with en route to you?
Well, here we are again.
This time, Ledger hardware wallets sold by an authorized reseller in Malaysia were found to have been modified with hardware capable of reading and transmitting the 24-word recovery phrases displayed during setup. Similar tampering has been reported elsewhere in the world, although these cases are so far unverified by Ledger. The attack has been linked to an estimated $93 million in cryptocurrency stolen.
The reseller, CryptoBilis, was acquired earlier this year, with the former CEO claiming a confidentiality agreement prevented former staff from revealing that the company was under new management. This has led to speculation that the purchasers themselves were involved in the attack, although there is no evidence of this yet.
The lesson here is that, once again, crypto is not ready for mainstream adoption. A few in the community will chide the victims for their naivety: sure, they bought a hardware wallet from an authorized reseller, but did they do a full teardown to ensure no additional components were added to the device? But I think many more will quietly recognize this as another case of people who did everything they were supposed to losing everything with basically no recourse.
Who needs a state to attack the food supply? · ↗ www.france24.com
The falling cost of attacking critical infrastructure
Hundreds of supermarkets in France suffered a cyberattack that heated freezers and fridges up to 50°C, sparking fires and mass food spoilage. Grocery stores from the conglomerate Ahold Delhaize operating in the Netherlands, Belgium, and Luxembourg also suffered a security incident around the same time, affecting its online app, delivery system, and electronic price tags. There is currently no indication whether these attacks were related.
The refrigeration units in the French supermarkets were from manufacturer Danfoss, which claims the affected units were “running outdated firmware”. Back in August, Claroty’s Team82 announced a vulnerability that would allow an attacker to perform just such an attack on refrigeration units using a remote web interface, although there is no indication so far that this specific vulnerability was exploited in this case.
Why are supermarket fridges connected to the internet in the first place? Remote monitoring and maintenance, apparently. But this also massively increases the attack surface, not just of individual stores and their profit margins, but of the food supply itself.
An uncomfortable reality is that a lot of critical infrastructure is more vulnerable than we would hope. Could this attack be a rehearsal for a larger attack by a hostile state or well-organized terrorist group? It reminds me a bit of the mysterious 2013 Metcalf sniper attack, in which unidentified gunmen cut communications cables and seriously damaged 17 transformers at a California electrical substation, then disappeared without a trace. Some feared it was just preparation for a larger attack that thankfully never came.
…Why I built an MCP server for Big Muddy
I recently decided to take a step to simplify my publishing workflow at Big Muddy. As previously described, Big Muddy is a Git-backed Hugo blog managed using Sveltia CMS, with post scheduling handled by a triggered GitHub Actions workflow.
A vital component of the Big Muddy workflow is the note: a temporary document visible only to me that I use to capture links or ideas and some surrounding context, in order to later use them to write an actual post.
In May, I added an intelligence layer to Big Muddy with a ZeroClaw personal agent running on my Raspberry Pi. The agent had one purpose: receiving a link or idea, adding some context through dialogue or web searches, and saving it as a temporary note to the Big Muddy repo.
Despite my documented struggles with ZeroClaw, this workflow was basically working for me. However, in parallel, I continued to use ChatGPT to research other notes and ideas, in a way that my ZeroClaw setup was not particularly well suited to carrying out (i.e., when the research required was extensive). But this left some ideas well-synchronized with the Big Muddy repo (from ZeroClaw) and some scattered about random ChatGPT threads, unless I manually turned them into temporary notes. Of course, I could always ask ChatGPT to do the transfer via the GitHub connector, but this wasn’t the ideal, fenced-in mechanism to do so.
…The other exception that proves the rule
Cicero’s exception that establishes the rule
In August, I wrote about how I learned the “true” meaning of the expression “the exception that proves the rule”, namely from an essay about mite incest by paleontologist Stephen Jay Gould. In that flavour of the expression, “prove” comes from the Latin probare, meaning to test. An exception can test a rule, for example, by identifying a case where the assumptions underlying the rule no longer hold. In Gould’s case, the rule that sex ratios in animals tend to be equal, except under certain conditions where the reasons for this pattern do not hold.
But there is another flavour of this expression that is more widely cited, derived from a legal defence by the Roman statesman and lawyer Cicero: exceptio probat regulam in casibus non exceptis (the exception proves the rule in cases not excepted). In other words, identifying an exception implies the existence of a general rule. For example, a sign reading “no parking on Sundays” implies that parking is permitted on other days, even if not directly stated.
The most common use remains dismissing a pertinent counterpoint to one’s argument as “the exception that proves the rule”.
Copy a webpage as a PDF to the clipboard on iPhone
Sometimes I want to share a webpage with an LLM on my iPhone but the page requires a login.
It turns out you can “print to PDF” directly to the clipboard on iPhone. This makes it easy to share whatever page you have access to with an LLM. This trick was probably obvious to everyone else, but I just discovered (well, probably rediscovered) it yesterday.
I use Firefox, but it should work in Safari or any other browser on your iPhone:
Share → Print → Share → Copy
Then you can paste it as a PDF into whichever app you like, without having to save an intermediate file.
Gray wolves with dire wolf characteristics
Apparently I missed this story last year: Colossal Biosciences has resurrected the dire wolf using CRISPR gene editing technology.
My first reaction: dire wolves aren’t just low-level D&D enemies? No, apparently they were an actual wolf species that went extinct around 10,000 years ago.
Second reaction: how did I miss this? Reviving ancient plants from preserved seeds or tissue is one thing, but de-extincting an animal? They tried it once with the Pyrenean ibex, which has the dubious distinction of being the only animal to go extinct twice. The cloned baby survived only a few minutes.
So, what happened with the dire wolf? Did they start from a reconstructed genome and maybe splice in a little wolf DNA to fill the gaps? No, they just took some gray wolf cells, made 20 edits across 14 genes to make them look a bit more dire wolf-like, and cloned them. They didn’t directly splice in dire wolf DNA at all, and a quarter of the edits weren’t even based on dire wolf DNA, but on ordinary variation in gray wolves.
Cool technology, but claiming to have de-extincted the dire wolf is just marketing.
Apparently the company is working on resurrecting the woolly mammoth too.
But where is my dire penguin? Giant prehistoric penguins were also real. Palaeeudyptes klekowskii, which lived in Antarctica some 37 million years ago, stood about 5'3" but weighed as much as Travis Kelce (~250 pounds).
…At least the mass deployment of personal agents will be funny
But also pretty dangerous.
We’re now at the point where my girlfriend’s Duolingo is being spammed with ads for Meta’s new user-friendly AI agent, Muse. Personal AI agents are finally becoming mainstream. While I think many people will initially struggle to find use cases (the launch video features the cliche of managing a flight, but of course the average person flies 0 times per year), I believe they will emerge over time. Consider this example from Matt Griswold:
My wife told her friends how I set up a @bot to handle weekly meal planning and grocery shopping, saving 2-3 hours per week.
The problem is that most people aren’t really going to know what they’re agreeing to when they sign up for Muse and give it the keys to the rest of their digital lives. We’ve already seen some stories of personal agents screwing up, ranging from amusing to alarming. Keep in mind that the people represented below are tech-savvy early adopters—and are thus more ambitious but also better equipped to deal with agents.
Don’t let your agent sell on Facebook Marketplace for you. [Matt Robb]
Tech YouTuber Matt Robb reported that Muse accepted a lowball offer from a prospective buyer, handed out his address, and told the would-be buyer that he was at home to meet them when he wasn’t. Unsurprisingly, this did not net him a positive review.
…An update on vote efficiency in Quebec · ↗ www.thewrit.ca
Quebec held an election two days ago, which saw the province’s sovereigntist Parti Québécois emerge victorious with 59 of 127 seats, five short of the 64 required for a majority. Meanwhile, the ruling CAQ collapsed from winning 90 of 125 seats (72%) in the 2022 election to zero this time around.
I wrote a post in April about vote (in)efficiency in Quebec, pointing out that the Parti Québécois won just 6 of 110 seats with 30% of the vote in the province’s 1973 election but could now plausibly win a majority with the same level of popular support.
What ended up happening Monday was that the Parti Québécois got 28% of the vote and carried 59 seats, five seats short of a majority. It was the lowest vote share ever for a winning party in the province; the previous low was the Parti Québécois’s 32% in 2012. It is also one of the lowest vote shares for a party forming government in Canadian history.
Part of the explanation is that this was an unusually fragmented election, with five viable parties splitting almost the entire vote. The second-place Liberals took just 24%, the Conservatives 21%, the CAQ 13%, and Québec solidaire 12%.
Éric Grenier from The Writ (also co-host of the excellent polling-focused podcast Les chiffres) points out that this was the first time in Canadian history, across all federal and provincial elections, that no party was able to capture at least 30% of the vote.
…Jev for social media fabulism · ↗ www.conspirator0.com
Jev is a new type of AI classifier ingesting natural language and outputting probabilities of three types: choices, scores, and yes/no. It promises similar performance to frontier LLMs but roughly two orders of magnitude faster and cheaper.
(Jev has been the talk of the town since it dropped on September 15, but I was travelling in the North when it came out. I first heard about it when a friend texted me, “oh they’re not talking about Jev in the Canadian Arctic?” I assumed “Jev” was the perfect joke name for whatever new thing in AI everyone was suddenly talking about, until I Googled it and discovered that Jev was, in fact, the new thing in AI everyone was suddenly talking about.)
Conspirador Norteño is a fun follow, an anonymous account sniffing out inauthentic social media accounts and bot networks. They used to focus on Twitter, but since that website shut off API access, they have focused more on Bluesky. Not long ago, they posted their particular use case for Jev: semi-automated identification of contradictory biographical statements from dubious Bluesky accounts.
Sensational accounts on social media frequently lie about their personal and professional lives (Reddit story accounts are perhaps the most extreme example of this phenomenon), and what Conspirador did was pull posts from a list of Bluesky accounts, use Jev to classify whether they contained biographical claims, then use Jev again to compare claims pairwise to determine if they contradicted each other. For example, inconsistencies in work history or claiming to have good knees in one post and bad knees in another.
…WeWorm · ↗ calif.io
The WeWorm exploit dropped by Calif Research about a month ago is pretty nuts: the first zero-click worm for WeChat, capable of gaining full control over a user’s WeChat account and subsequently attacking everyone on that user’s contact list.
For those of you who have never heard of WeChat, it is China’s “everything app”: used for payments, messaging, and social media. It is also deeply embedded in China’s censorship and surveillance infrastructure. As such, gaining control over a user’s WeChat account gives an attacker a lot of power.
The exploit discovered by Calif researchers is about as bad as it gets. For the attack to work, the target must be on the “friend list” of the attacker, but the target is not required to answer the malicious call or interact with it in any way. While hanging up on the call blocks the exploit, an attacker can simply call again at a time when the user is unlikely to be awake. When account control is achieved, the compromised account can begin targeting all the users on the victim’s friend list. The attack can potentially be chained with other exploits to gain complete control over a victim’s iPhone or Android device.
Calif said they developed this attack with AI assistance, and they only published it after confirming that Tencent, the creator of WeChat, had fixed the exploit. There is no evidence that this exploit was used in the wild. But Calif says its AI found the bug and helped write the first remote-code-execution exploit in about two days, with the worm taking another week to build. That speed speaks to the new era of online security in the age of incredibly capable AI coding tools.
…Bring on the spending caps · ↗ simonwillison.net
Cloud provider bills should not come with unlimited downside
Simon Willison has a good post arguing for hard budget caps by default on pay-for-usage services and APIs. Large compute providers like AWS and Google Cloud have traditionally used soft caps, i.e., you receive an email at 2 AM warning that your spending has reached 80% of your limit, and then you wake up to a $2,000 bill after some bot finds your demo or (more optimistically) it goes viral.
Thankfully, both cloud providers have recently introduced hard spending caps. For disposable projects, demos, experiments, etc., I’ve always liked the prepaid-credit and per-key spending caps of services like OpenRouter, but these changes make the big cloud providers more viable for these use cases.
There’s a discussion of the article on Hacker News, with commenter motionlessveloc arguing that hard budget caps are a nightmare for businesses that need to provide reliable services:
It was, unfortunately, a nightmare. There were tons of tickets and even threats of lawsuits from customers whose service got cut off hard at the worst possible time due to organic growth/going viral/big event/nobody knew about the limit/etc. Not only did they lose all the leads and revenue they would have gotten from that bump, but they also pissed off their own existing users who suddenly couldn’t use the service either.
Generally speaking, it’s much better to use alerts instead of hard limit. Even in the worst case (hackers pwn your credentials and mine Bitcoin or whatever) the rest of your business is unaffected and you can negotiate with the billing department at comparative leisure.
…
The AI hacking committee · ↗ www.wired.com
Lily Hay Newman over at Wired has an interesting report on an apparently autonomous hacking tool dubbed CLOSEDQUORUM, citing an investigation by Cisco Talos. The command-and-control infrastructure polls four LLMs (DeepSeek, Qwen, Mistral, and Google Gemini) to develop a consensus on what to do next.
The tool, as discovered by researchers, was non-functional, populated only with dummy values for the LLM API keys and Discord key (stolen credentials would be forwarded to said Discord server). The binary they analyzed traces back to posts made in 2025 by a user of a forum dedicated to stolen credit cards.
No in-the-wild deployment has so far been confirmed, but we can be pretty sure that autonomous cybercrime tools like this will start popping up soon.
Near-disaster at Los Alamos · ↗ www.science.org
Eight plutonium rods, too close for comfort
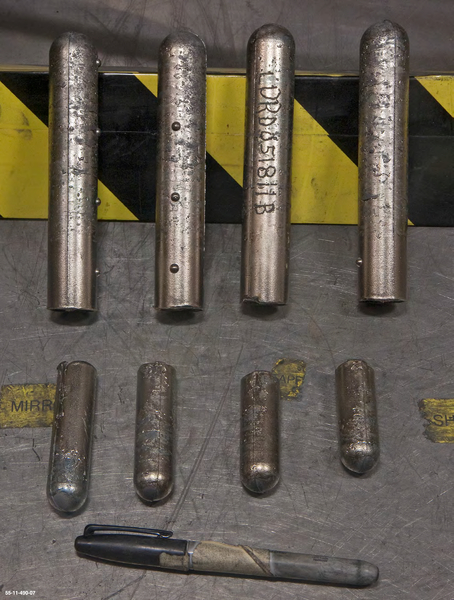
Photo from Los Alamos National Laboratory/U.S. Department of Energy.
Science has a well-reported story on a near-disaster in Los Alamos National Laboratory’s PF-4 plutonium laboratory building in 2011. As seen in the picture above, technicians decided to arrange eight plutonium rods on a table, only inches apart, in order to photograph them (simply because they looked nice). Luckily, a supervisor returned from lunch, noticed the display, and ordered the rods moved farther apart. This averted a potential nuclear chain reaction—a “criticality” event—but the building was not evacuated as protocol dictated (humans reflect neutrons, increasing the likelihood of a chain reaction).
Over the next two years, almost all of the engineers dedicated to avoiding criticality events would quit, which led in 2013 to portions of the lab being shut down for nearly four years, likely at huge cost to American taxpayers. The 2011 incident was far from the facility’s first, with accidents stretching all the way back to the facility’s opening as part of the secretive Manhattan Project in World War II. The most famous accidents were the two fatal criticality incidents involving the so-called demon core in 1945 and 1946, which killed two scientists.
The good news is that the famed laboratory’s safety standards have genuinely improved since reopening fully in 2017. It only took a near-disaster to do so.
Please call it Harness/LLM
Melanie Mitchell points out that nobody really uses LLMs by themselves anymore. What we call ChatGPT or Claude is an amalgamation of a model, post-training, safeguards, and an ever-more-elaborate software harness.
I’d just like to interject for a moment. What you’re referring to as an LLM, is in fact, Harness/LLM, or as I’ve recently taken to calling it, Harness plus LLM. An LLM is not a AI system unto itself, but rather another component in a fully functioning software harness made useful by the system prompt, context management, tool loops, safeguards and vital system components comprising a full AI system as defined by ISO/IEC 22989.
Through a peculiar turn of events, the whole system is often simply called an “LLM.”
Please use the technically correct term: Harness/LLM.
(The above is a dumb joke post based on the infamous “I’d just like to interject” copypasta attributed to Richard Stallman.)
Knowing when not to guess
ChatGPT needs to know when to just use reverse image search
About a month ago, I wrote about a specific AI failure where ChatGPT confidently misidentified an image of a scene from Once Upon a Time in the West as coming from Jaws. Recognizing that the genre of pointing and laughing at AI fails got tired years ago, I reflected on my renewed capacity to be disappointed by AI failure—not because the capabilities of the technology did not match the hype, but because AI has actually gotten so good that failure at such a mundane task is genuinely surprising.
Out of curiosity, I tried the task again in a temporary, unpersonalized chat. Once again, ChatGPT (5.6 Sol High) misidentified the source of the image, this time as Sleuth (1972), citing elements not actually present in the scene:
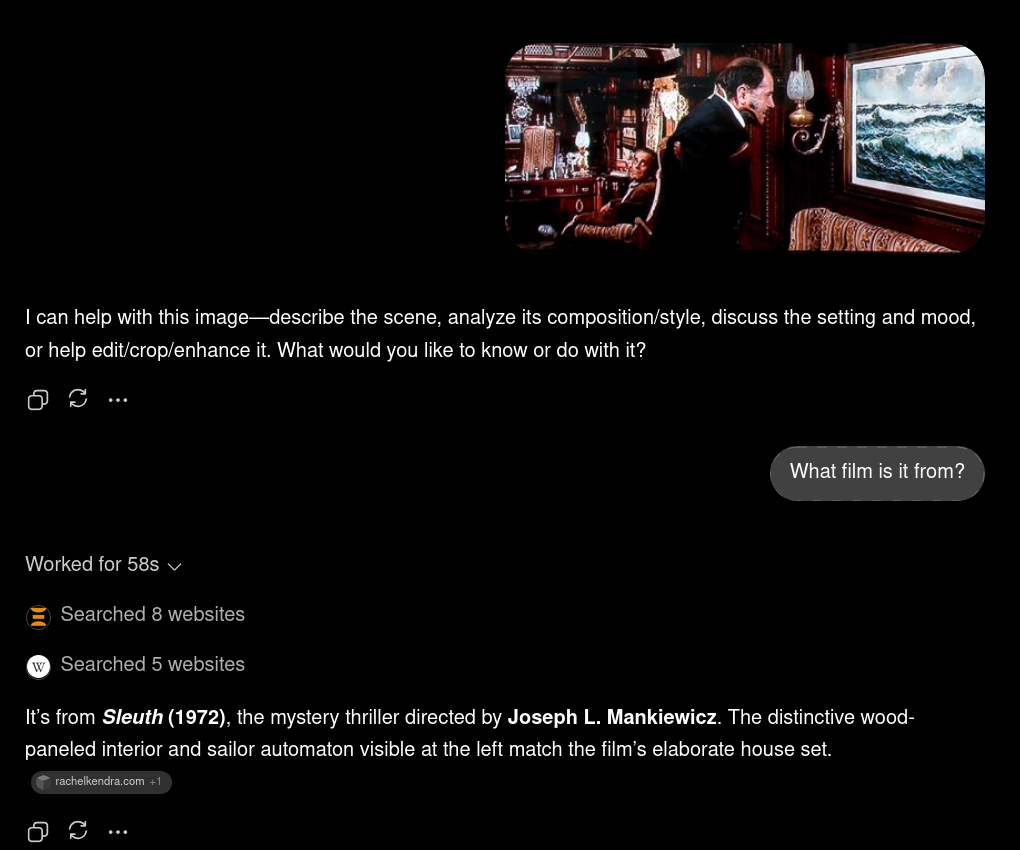
The model even searched 13 websites as part of generating its response. None of those, apparently, was a reverse image search, which would have immediately identified the source of the image. Google, of course, identifies it immediately:
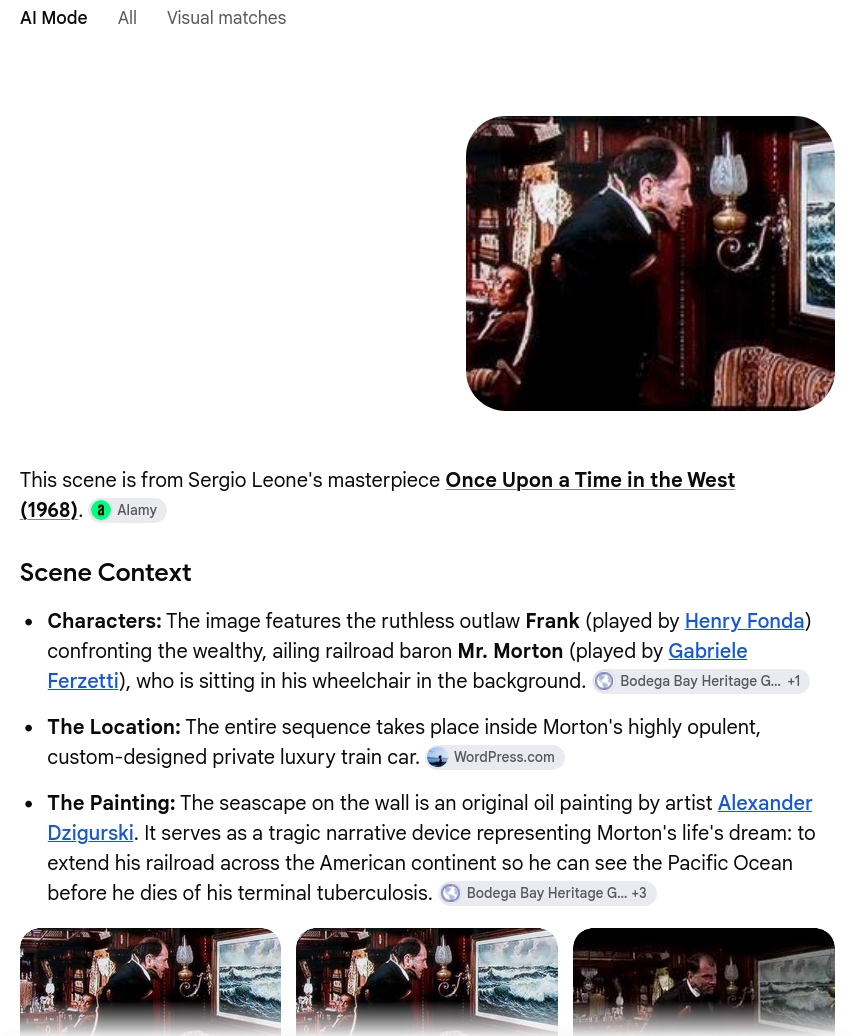
As detailed in the original post, I lifted this image directly from a publicly indexed and accessible website; I didn’t screenshot it from a YouTube clip or something.
…AI-generated posters don’t have to be bad (but often are) · ↗ john.hartnup.uk
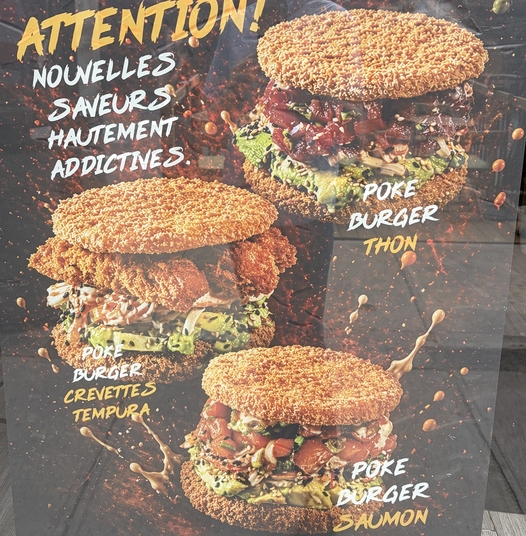
Everyone must have noticed the torrent of restaurants featuring pictures of weird, gross-looking AI-generated food that in no way resembles what you are served (usually for the better).
Here are some examples from my city this summer.
The slop burger:
And the slop biryani, which is more perplexing than gross:
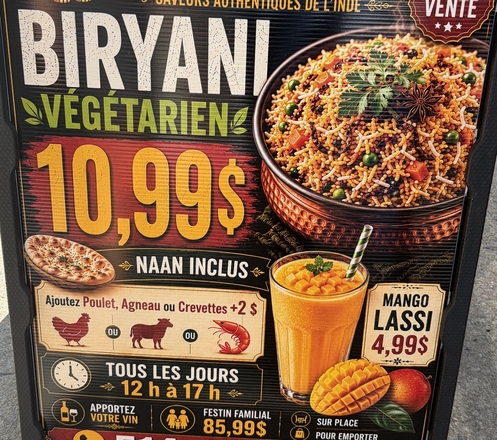
Of course, we’ve all seen way worse examples. Those are just the ones I happened to have on my camera roll. Even the “good” examples of AI food images tend to have an uncanny, slightly unsettling quality. Certainly no restaurant should be completely fabricating what its food looks like, but it has unfortunately become normal to shamelessly lie about the nature of your core product. What surprises me is that the bar for what restaurants will use to advertise their business is so low.
I am sure someone will come along to tell me that the newest models have fixed this, but I bet we will continue to see these repellent AI ads from clueless restaurant owners for some time to come.
Anyway, this post isn’t actually about AI slop food pictures; I just wanted an excuse to dump those screenshots in the preamble.
…Truth to pain · ↗ freddiedeboer.substack.com
Freddie deBoer is an essential writer because he often writes about subjects that few others are willing to touch. Earlier this month, he wrote a piece motivated by a recent article in New York magazine claiming that the scale of illness related to the September 11 terrorist attacks is likely much greater than is currently recognized. He pointed out that the epidemiological evidence in the piece falls far short of the usual standards for such a prominent outlet reporting on a topic of such importance. Freddie’s piece is a good and necessary one and you should read it.
The fundamental problem is: nobody wants to tell people who are suffering that they might not be right about the source of their pain. Questioning someone’s explanation of their suffering feels like you are questioning the suffering itself. But if no one can speak honestly about an issue, then how are we supposed to make good policy and direct limited dollars for treatment and research in the right direction?
I believe many people working in health research have one or more conditions they avoid speaking about because the communities formed around them have developed such powerful norms around what can and cannot be questioned that they figure it simply isn’t worth the backlash.
And yet the truth is what we owe people in pain, as deBoer concludes his piece:
…Polling has become harder (and faker) than ever · ↗ www.theargumentmag.com
The incentives for bad polls are strong
Charlotte Swasey has a good piece over on The Argument on how difficult it has gotten to accurately poll the public (and how easy it has become to poison the discourse with dubious or outright fake polls).
In the golden age of polling—maybe the late 80s to the early 90s—when everyone had landlines and most people would pick up the phone, polling was pretty easy to do: just randomly dial numbers and survey a random adult in the household. Sure, it was labour-intensive, and you still had non-response bias. But for the most part, you could pay people a bunch of money to make a lot of calls, then make a few straightforward adjustments for who responded and assume your resulting survey was relatively representative of the population you were trying to make inferences about.
None of that is true today.
While it has gotten easier and cheaper than ever to survey the public through any number of firms offering online panels, actually interpreting these results is extremely difficult because respondents are extremely self-selected. At the same time, this reduced barrier to entry has made it extremely easy for activist organizations to produce favourable-but-dubious polls to drum up headlines or mollify their donors.
Companies are even releasing fully AI-generated survey samples, often without clearly labelling that the results are purely fabricated.
…AI overwhelms one researcher’s scientific bug bounty · ↗ x.com
Biologist Ruben C. Arslan has a standing bug bounty for errors in his scientific works. Or had, until AI agents overwhelmed his GitHub repository with bug reports, a few days after the release of GPT-6 Astra.
Supposedly, one guy found the repository after prompting his agent “make me 50 USD make no mistakes”.
On the one hand, it’s good for the scientific process to become more self-correcting. On the other hand, it’s bad for AI to place overwhelming demands on researchers’ scarce attention in yet another domain of research, this time with potentially dubious or low-quality reports of scientific errors.
I imagine much of this agent review will eventually move to the submission and pre-submission phases of scientific research, so that human review can be reserved for a smaller number of higher-quality research outputs.